Machine Learning Techniques in Microservices: A Systematic Mapping

Microservices architectural design has become increasingly popular due to the enhanced scalability, flexibility, and maintainability of large and complex applications. Machine learning (ML) has emerged as a powerful tool in microservices deployment and management. Although ML techniques have been useful for building microservices-based system architectures, the current literature does not provide clear guidance on which ML techniques developers of these systems might use. This research describes the design and results of a systematic mapping study to identify the ML techniques used in the building of microservices-based systems. The review yielded 193 articles, of which 34 primary studies were selected. Key findings are: (i) Monitoring, diagnostics and observability (MDO) and Resource orchestration and management (ROM) are the most used domains; (ii) Deep Learning (DL) and Unsupervised Learning (UL) are the most used techniques; (iii) Proposed solutions validated through evaluative research dominate the field; (iv) Case studies and experiments are the main empirical strategies; and (v) Public data sets are limited. This effort will enable developers to effectively address the refinement and improvement of software designs using ML methods.

This research will be presented in International Conference of the Chilean Computer Science Society (SCCC)

Learning and Predicting Competitive Tumor-Immune-Normal Cell Dynamics Using Physics-Informed Neural Networks

Modeling tumor progression and immune response is a key challenge in computational oncology. Traditional ODE-based models offer insights into interactions among cancerous, healthy, and immune cells, but often rely on ideal assumptions and dense data. In this research we explored the use of Physics-Informed Neural Networks (PINNs) to learn and predict the behavior of a nonlinear system modeling tumor-immune-normal dynamics. By embedding biological equations into the learning process, PINNs can train on sparse or noisy data while respecting domain constraints. We assess their performance under varying data availability, showing that moderate training data enables accurate reconstruction and extrapolation, whereas excessive data may induce localized errors. These findings suggest that PINNs are promising tools for biomedical modeling, with potential applications in personalized simulation and treatment planning.

This research will be presented in International Conference of the Chilean Computer Science Society (SCCC)

Security Discussions in Quantum Software Projects on GitHub

Quantum software engineering is an emerging field that leverages quantum computing and software development to address contemporary computational challenges. A significant concern in this domain is security, which has become a critical issue in quantum software engineering. Despite advances in quantum computing security, there is a lack of empirical evidence examining the primary security concerns of developers within the context of quantum software engineering. This paper presents a study that identifies, describes, and analyzes topics discussed by developers regarding open and closed issues of quantum software projects hosted on GitHub. Of the 18 identified projects, 2,264 filtered open and closed issues were obtained, of which 294 (13\%) were related to security. Using the Latent Dirichlet Allocation algorithm, 15 topics were identified. Furthermore, we identified the key security concerns that developers addressed in the issues, the majority of which were oriented towards code failure, noise and modular validation. This study serves as a precedent for a practical analysis of the identification and characterization of security topics, as well as the initial insights into security design decisions that developers discuss in quantum software projects.

This study will be published in the Journal of Systems and Software

Defining a Modifiability Scenario for Quantum Software

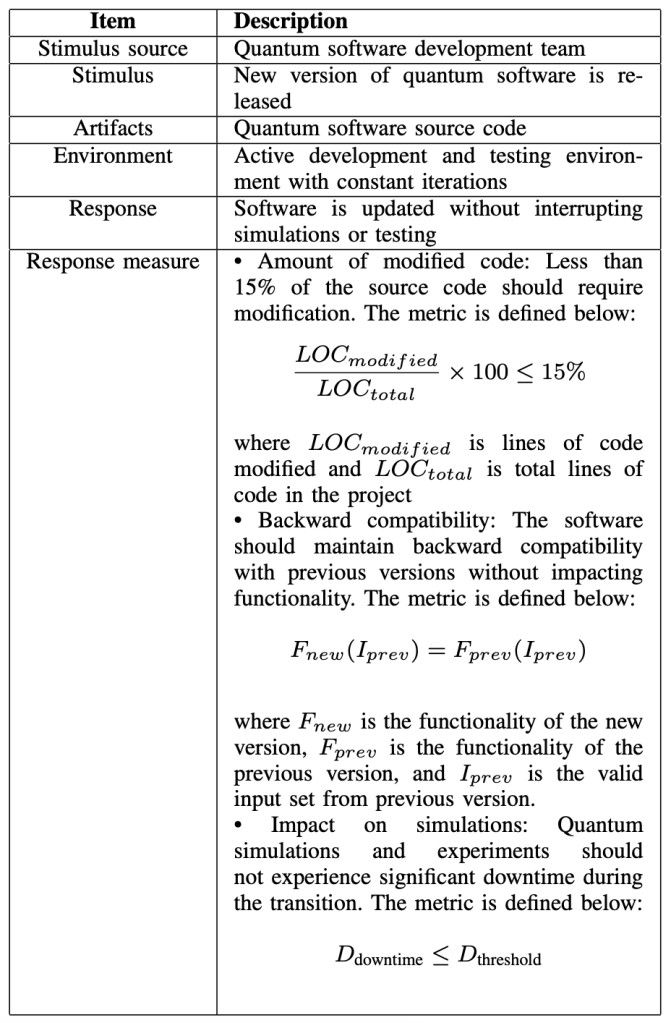
Quantum software engineering aims to establish methodologies, tools, and frameworks to support the development of functional and maintainable quantum applications. A critical aspect within this domain is the maintainability of quantum software, which pertains to the system’s capacity for modification, correction, or evolution over time. Modifiability is particularly significant as it encompasses mechanisms that enable software to be altered effectively and efficiently without introducing defects or compromising quality. Despite its importance, there has been limited discussion on addressing modifiability in quantum software. Moreover, there is little information on studies that translate maintainability concerns into specific modifiability scenarios. In this paper, we present our investigation about defining a modifiability scenario for quantum software, characterized by sources of stimuli, stimuli, software artifacts related to modifiability, environment, responses to the stimuli, and measures of those responses. We examined the release and version histories of 18 quantum software projects to extract data from each version. Preliminary findings outline the development of a concrete modifiability scenario for quantum software that facilitate the implementation of the defined responses within the modifiability scenario in quantum software.

This study will be published in IEEE Xplore and presented at CLEI 2025

Framework to Support Students in Defining DevOpsTechnology Stacks

DevOps is an approach to automated software development and deployment that combines development and operations, with the goal of improving collaboration between teams to optimize the software lifecycle processes, from planning and development to testing, deployment, and monitoring. Despite being an innovative approach, DevOps presents a significant challenge for students in understanding and implementing software development projects. This challenge includes understanding the problem to the solution abstraction that contemplates the design, implementation, and automation of the software development process. This study proposes and evaluates a methodological framework to support students in defining DevOps-oriented technology stacks.
The framework combines software architecture and software engineering practices that collectively provide a learning approach based on design decision-making and selection of technologies, frameworks, and tools. We evaluated the framework in two iterations of a capstone course, using a case study that considered the implementation of a DevOps stack on (i) a pre-existing system and (ii) a system from scratch. Results show that students who implemented a DevOps-oriented stack on systems developed from scratch were successful, but those who implemented it on a pre-existing system confronted challenges in configuration management and system flexibility. The proposed framework facilitates the pedagogical experience of implementing DevOps in software development projects, thus rendering it beneficial for students.

This study will be published in IEEE Xplore and presented at CLEI 2025

Using implementation science to develop and deploy an oncology electronic health record

The management of oncology clinical processes involves the efficient management of data using electronic clinical records to effectively monitor and treat oncology patients. As the process of treating and monitoring cancer patients involves multiple stakeholders with differing perspectives, the implementation and deployment of oncology clinical registries represent a significant challenge. In this study, we address this complexity by employing a technique that helps translate implementation strategies into requirement identification methods, which are subsequently disseminated throughout the implementation and deployment phases of health information systems. We applied this technique to develop an electronic health record for the national cancer plan in Chile. The findings indicate that six implementation strategies are essential to addressing stakeholder needs, as well as three requirement identification techniques to describe the underlying problem. Furthermore, a study conducted with 27 stakeholders revealed that the perception of the oncology electronic clinical record has considerable acceptance in three critical functionalities related to the clinical process of oncology patient management. The use of implementation science strategies provides an alternative approach to understanding the underlying problem that stakeholders face when they require healthcare technologies.

Link of the paper

CLEI 2024: Zero Trust Architecture and Quantum Software Engineering

Last week CLEI was held in Argentina. We had the opportunity to present a paper related to Zero Trust Architecture and a talk about our advances in Quantum Software security.

About Zero Trust Architecture:

Zero Trust Architecture (ZTA) is a novel security approach for building secure systems.
ZTA-based systems are built with specific security mechanisms to enforce their basic tenets, for example, explicit verification and least privilege. Although existing security mechanisms have been useful in building ZTA-based systems, the current literature does not provide clear guidance on which security mechanisms should be used by developers of these systems. This article describes the design and results of a systematic mapping study to identify the security mechanisms used in the building of ZTA-based systems. The review yielded 290 articles, of which 30 primary studies were selected. Key findings are: (i) 24 different security mechanisms were reported; (ii) 37\% of them are classified into access control techniques to implement ZTA least priveleges tenet; (iii) ABAC and AIM are the most used mechanisms; (iv) over half of security mechanisms (69\%) focus on resisting attacks (instead of detecting or recovering); and (v) experimentation is a predominant empirical strategy within ZTA security research. The identification of these security mechanisms will enable developers of ZTA-based systems to effectively address the security challenges associated with implementing ZTA tenets.

About Quantum Software security:

In this talk at the first Latin American Workshop on Quantum Software Engineering we describe our research progress on the secure design decisions we have detected in quantum software by identifying topics in quantum software projects on Github.

Evaluation of Machine Learning Techniques for Classifying and Balancing Data on an Unbalanced Mini-Mental State Examination Test Data Collection Applied in Chile

The Mini-Mental State Examination (MMSE) is the most widely used cognitive test for assessing whether suspected symptoms align with cognitive impairment or dementia. The results of this test are meaningful for clinicians but exhibit highly unbalanced distributions in studies and analyses regarding the classification of patients with cognitive impairment. This is a complex problem when a large number of MMSE tests are analysed. Therefore, data balancing and classification techniques are crucial to support decision-making in distinguishing patients with cognitive impairment in an effective and efficient manner. This study explores machine learning techniques for data balancing and classification using a real unbalanced dataset consisting of MMSE test responses collected from 103 elderly patients participating in a Chilean patient monitoring project. We used 8 data classification techniques and five data balancing techniques. We evaluated the performance of the techniques using the following metrics: sensitivity, specificity, F1-score, likelihood ratio (LR+ and LR-), diagnostic odds ratio (DOR), and the area under the ROC curve (AUC). From the set of data balancing and classification techniques used in this study, the results indicate that synthetic minority oversampling and random forest balancing techniques improve the accuracy of cognitive impairment diagnosis. The results obtained in this study support clinical decision-making regarding early classification or exclusion of older adult patients with suspected cognitive impairment.

The paper was published in IEEE Access

Inclusion of individuals with autism spectrum disorder in Software Engineering

Software Engineering is dedicated to the systematic and efficient development of software, which necessitates the active participation of all team members and a recognition of their unique skills and abilities, including those with autism spectrum disorders (ASD). The inclusion of individuals with ASD presents new perspectives, yet there is a lack of systematic evidence regarding the primary obstacles and potential benefits associated with their inclusion. This paper aims to identify, characterize, and describe barriers, facilitators, and methodological proposals described by the community to include individuals with ASD in the discipline of Software Engineering. We conducted a comprehensive systematic multivocal mapping study to evaluate the existing evidence on the inclusion of individuals with ASD in Software Engineering. We obtained 34 primary studies from which we identified the main facilitators of motivation to learn new skills, attention to detail, and the ability to report and visualize patterns. In contrast, the main barriers detected were communication, a lack of neurodivergent computational thinking, and sensory integration. Additionally, we identified and classified four categories of proposals that allowed the inclusion of individuals with ASD: (i) using virtual reality, (ii) creating more inclusive workspaces, (iii) encouraging neurodivergent computational thinking, and (iv) improving social skills. This study identifies the principal elements that ought to be taken into consideration when allocating tasks and roles to individuals with ASD in software development.

The paper is published in Information and Software Technology

Design of an Electronic Health Record for Treating and Monitoring Oncology Patients in Chile

Identifying the clinical needs to evaluate and manage the treatment and monitoring of cancer patients is a multidimensional challenge in healthcare institutions. In this regard, electronic health records (EHRs) are beneficial for managing clinical information; however, EHRs focused exclusively on patients with cancer have not been sufficiently adopted. In Chile, the need for oncology EHR has only been briefly addressed, resulting in insufficient updated and systematized information on oncology patients. In this paper, we propose the design of an oncology EHR that manages critical variables and processes for the treatment and monitoring of patients with cancer in Chile. We used a systematic methodology to design a software architecture oriented to focus groups and interviews to elicit the requirements and needs of stakeholders. We created and described an EHR design that considers four modules that group and manage the main variables and processes that are critical for treating and monitoring oncology patients. Enabling and designing a treatment and monitoring registry for cancer patients in Chile is essential because it allows for the evaluation of strategic clinical decisions in favor of patients.

This paper can be found in IEEE Access